Python computation
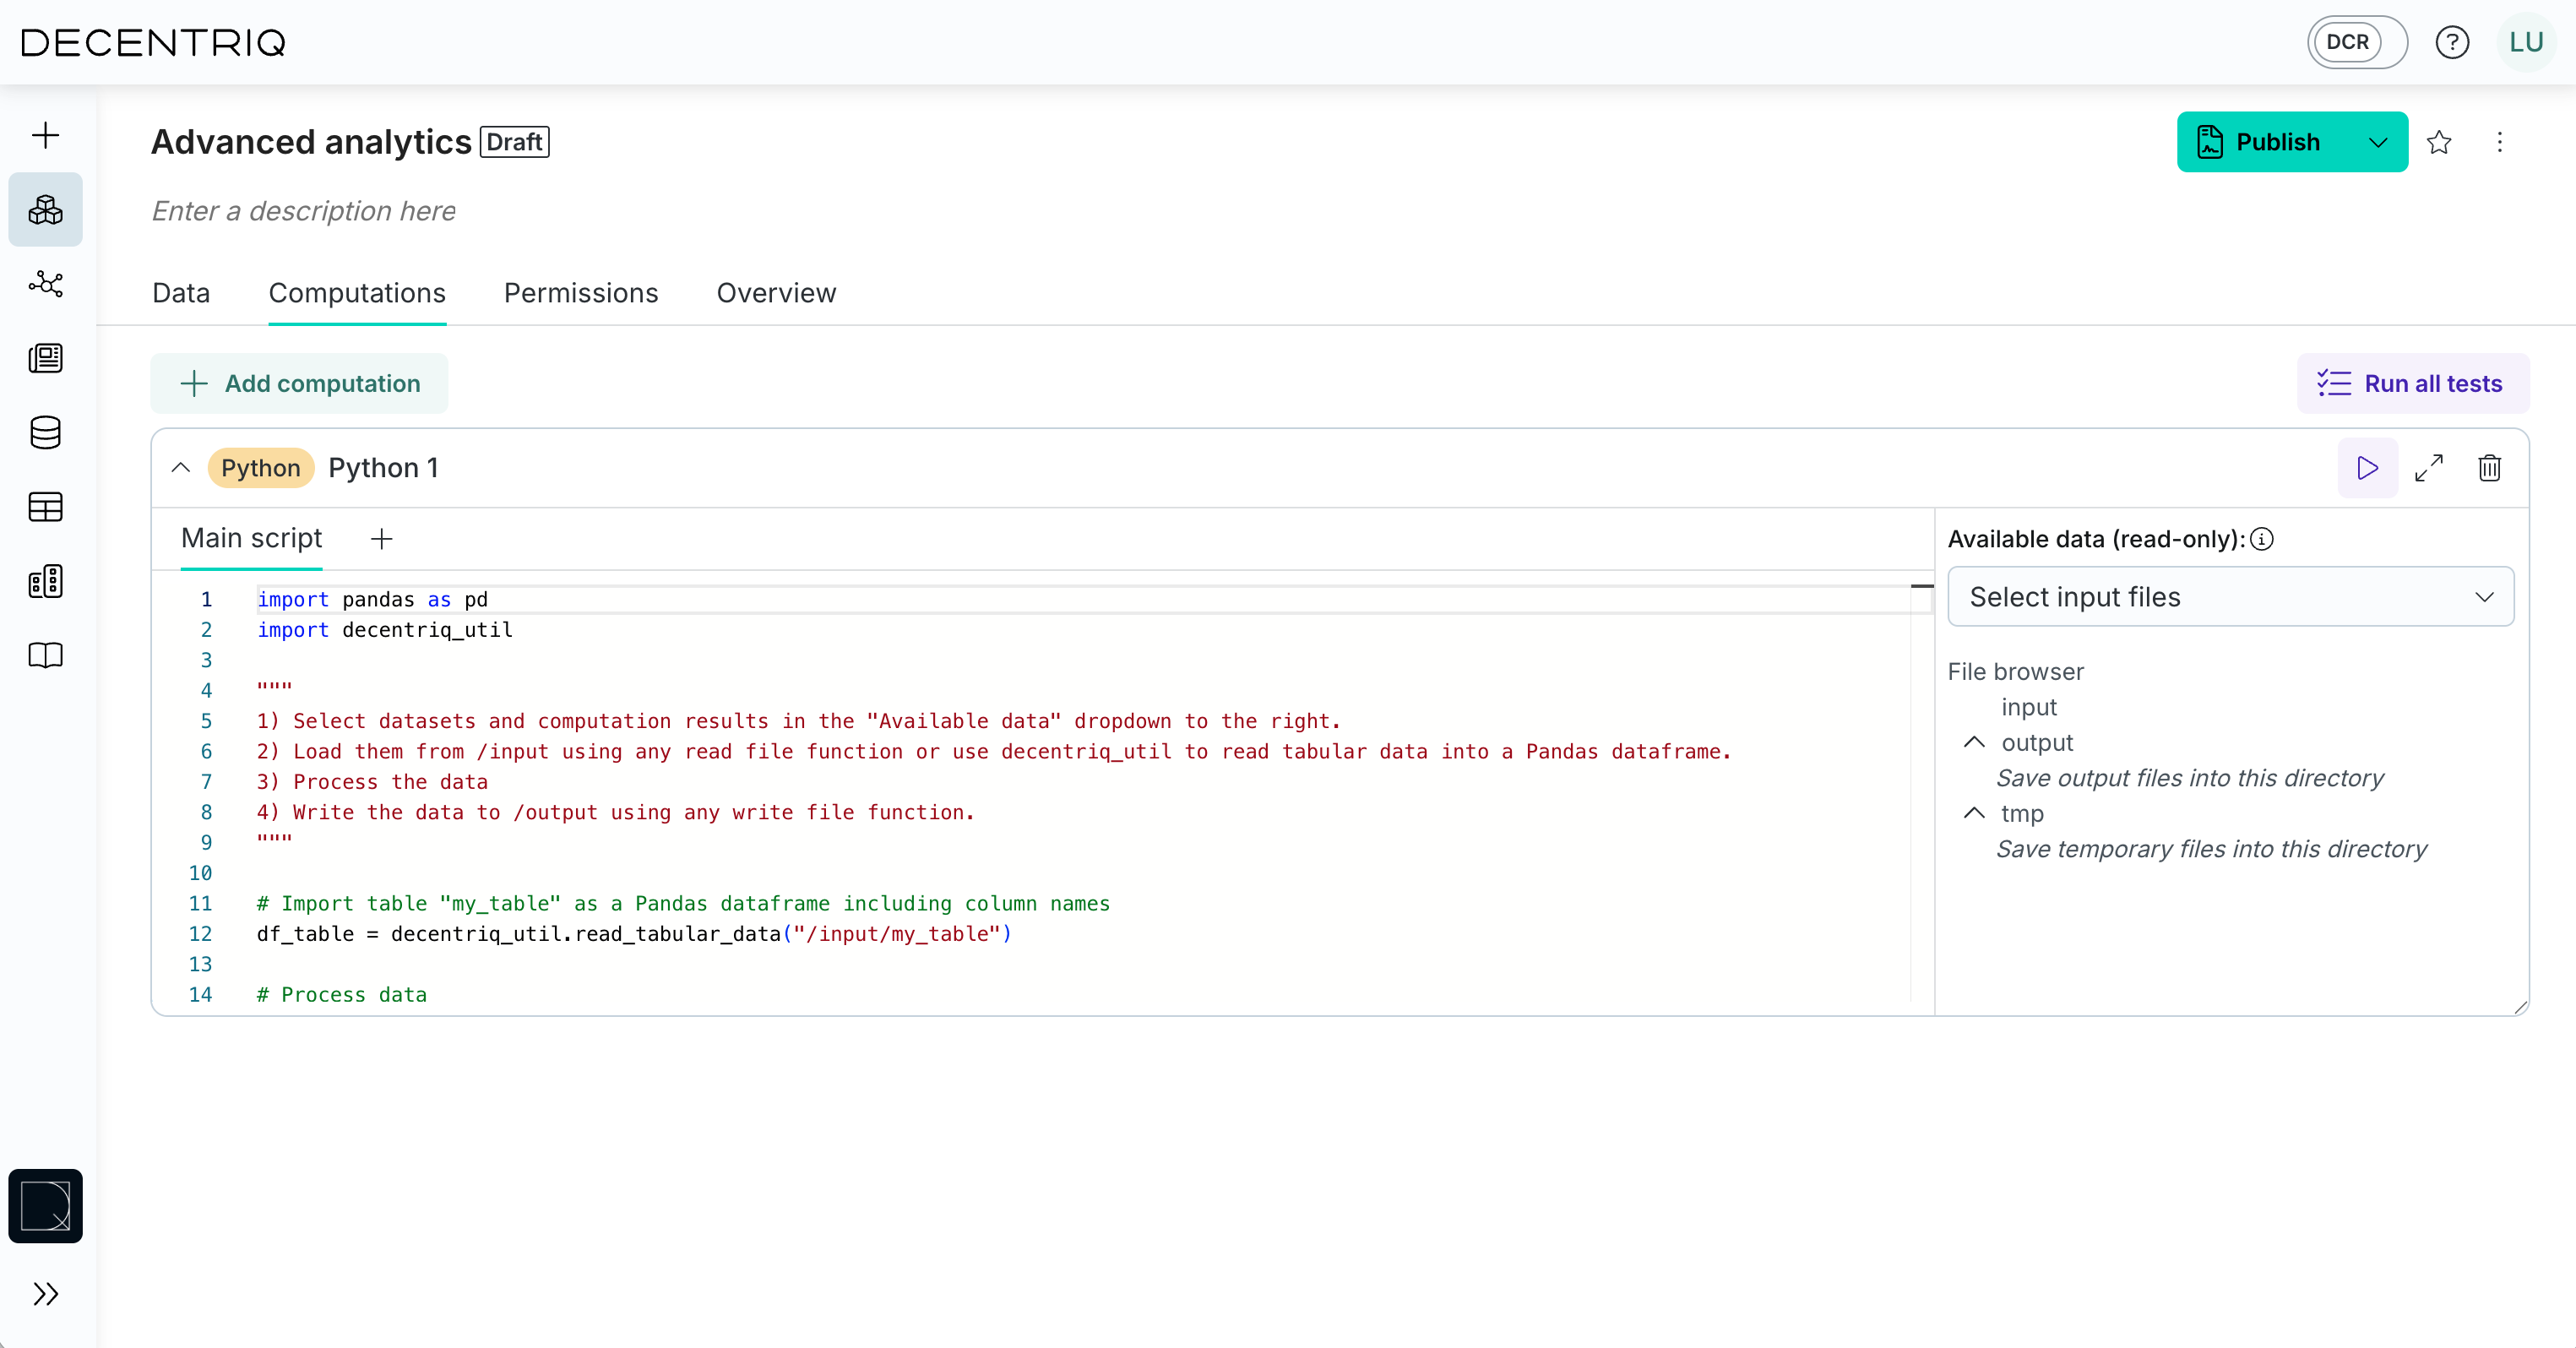
The Python computation reads from /input and writes results to /output.
It can execute standard Python 3.11.6 code with the following supported libraries.
Python version: 3.11.6
Library versions
zipp 3.16.2zict 3.0.0yarl 1.9.2xgboost 2.0.1wrapt 1.14.1watchdog 3.0.0validators 0.22.0urllib3 2.0.7tzlocal 5.0.1tzdata 2023.3typing_extensions 4.7.1tqdm 4.66.1tornado 6.3.3toolz 0.12.0tomlkit 0.12.1toml 0.10.2tifffile 2023.8.30threadpoolctl 3.1.0tenacity 8.2.3tblib 2.0.0tabulate 0.9.0sympy 1.12streamlit 1.28.1statsmodels 0.14.0sortedcontainers 2.4.0smmap 5.0.0smbprotocol 1.11.0smac 1.3.3six 1.16.0setuptools 68.2.2.post0seaborn 0.13.0scipy 1.11.3scikit-survival 0.22.1scikit-learn 1.3.0scikit-image 0.21.0ruamel.yaml.clib 0.2.7ruamel.yaml 0.17.32ruamel.base 1.0.0rpds-py 0.10.3rich 13.5.2requests 2.31.0referencing 0.30.2qdldl 0.1.7.post0pyzmq 25.1.1pytz-deprecation-shim 0.1.0.post0pytz 2023.3.post1python-gnupg 0.5.1python-dateutil 2.8.2pyspnego 0.9.2pyspark 3.5.6pyrfr 0.8.2pyreadstat 1.2.4pyparsing 3.0.9pynisher 0.6.4pydeck 0.8.0b4pycparser 2.21pycares 4.3.0pyasn1 0.5.0pyarrow 14.0.1py4j 0.10.9.7py 1.11.0psutil 5.9.6protobuf 4.24.4poetry-dynamic-versioning 1.0.1patsy 0.5.3partd 1.4.0paramiko 3.3.1pandas 2.1.1packaging 23.1osqp 0.6.3openpyxl 3.1.2olefile 0.46numpy 1.26.1numexpr 2.8.6networkx 3.1multidict 6.0.4msgpack 1.0.5mpmath 1.3.0mdurl 0.1.2matplotlib 3.8.0markdown-it-py 3.0.0lz4 4.3.2lxml 4.9.3locket 1.0.0lime 0.2.0.1lifelines 0.27.8liac-arff 2.5.0lazy_loader 0.3kiwisolver 1.4.5jsonschema-specifications 2023.7.1jsonschema 4.19.0joblib 1.3.2jdcal 1.4.1interface_meta 1.3.0importlib-metadata 6.8.0imbalanced-learn 0.11.0imageio 2.33.0idna 3.4gssapi 1.8.3gitdb 4.0.10future 0.18.3fsspec 2023.10.0frozenlist 1.4.0formulaic 0.6.6fonttools 4.42.1faust-cchardet 2.1.19et-xmlfile 1.1.0emcee 3.1.4ecos 2.0.11dunamai 1.18.0dq_sql_worker 0.1.0distro 1.8.0distributed 2023.10.0defusedxml 0.7.1decorator 5.1.1decentriq_util 0.1.0ddt 1.6.0dask 2023.10.1cycler 0.11.0cryptography 41.0.3contourpy 1.1.0cloudpickle 2.2.1click 8.1.7charset-normalizer 3.2.0cffi 1.16.0certifi 2023.7.22faust-cchardet 2.1.19cachetools 5.3.0brotlicffi 1.1.0.0bottle 0.12.25blinker 1.6.2bcrypt 4.0.1autograd-gamma 0.4.3autograd 1.6.2auto-sklearn 0.15.0attrs 23.1.0async-timeout 4.0.3astor 0.8.1altair 5.1.2aiosignal 1.3.1aiohttp 3.8.6aiodns 3.0.0Pympler 1.0.1Pygments 2.16.1PyYAML 6.0.1PyWavelets 1.4.1PyNaCl 1.5.0Pillow 10.1.0MarkupSafe 2.1.3Jinja2 3.1.2GitPython 3.1.37Cython 0.29.36ConfigSpace 0.5.0Brotli 1.1.0Babel 2.12.1
Note that by default the Python computations cannot access the network or internet. Also note that GPU-computations are currently not supported.
Input
The Python computation can access data from datasets and computations which have been listed as its dependencies in the Available data section from the /input directory.
The paths differ based on the type of the dependency:
- A Table dataset
Table 1can be loaded as/input/Table 1/dataset.csv - A File dataset
File 1can be loaded as/input/File 1 - The results of a depending Python or R computation can be loaded under
/input/<computation name>/<filename>the same way those results have been written to/output/<filename>in the depending computation - The results of a SQL computation can be loaded under
/input/<computation name>/dataset.csv
Note that /input is slow remote-backed storage. Computations that read from it repeatedly or do a lot of random access on it will be slow — copy the data to /scratch first in that case (see the Scratch section below), and read /input directly only for a single pass.
Output
The computation should write results to the /output directory. The results as well as any text streamed to stdout are accessible by all users with data analyst permission on the computation.
Scratch
Computations can write temporary data to the /scratch directory, a fast encrypted SSD with around 800 GB of usable space. Unlike the slow remote-backed /input and /output directories, /scratch is fast local storage. Data written there is always encrypted and is deleted after the computation has run, so it's safe to use for sensitive intermediate data.