Audiences
This tab is available if at least one of the collaboration types Remarketing audiences, Exclusion targeting, AI lookalike audiences, or Rule-based audiences is enabled in the Media DCR and you have at least one of the Create audiences or Export audiences permissions.
As soon as both, seed and base audiences, have been provided, the audience creation is prepared. This may take up to several hours, depending on the data size. Once completed, the audiences tab is accessible.
Automatic precomputation
The Media DCR includes many different computation paths, for example:
- Computing the list of advertiser seed audiences in the advertiser data (used in the overlap/insights/audience building selectors)
- Computing the overlap statistics
- Computing insights
- Computing audience sizes (and underlying audience lists) for all audiences shown in the Audiences tab
- Computing lookalike models (and their statistics) for all advertiser seed audiences such that quality curves can be shown when a lookalike seed audience is selected
- Computing selectable values in the rule-based audience builder
When a publisher changes their datalab or an advertiser changes their seed audience data (or provision them for the first time), all these results change. As these computations typically take several hours, we try to precompute as much as possible right on data change such that users using the Media DCR afterwards have minimal waiting time.
We decided to precompute all these computation paths on every change, except for the automatic computation of lookalike models which is a very expensive operation. Some of the seed audience datasets include 20-30 seed audiences, therefore resulting in 10+ hours of compute and blocking the Media DCR and the cluster. At the same time, we’d like to provide users with a set of precomputed lookalike models at all times. We therefore precompute according to the following rule
Precompute all computation paths (1)-(4) & (6)
Precompute lookalike models in (5) according to
# of precomputed lookalike models = 3 − number of lookalike audiences precomputed in (4) (minimum 0)
We will precompute in the following order (each sorted alphabetically within this group), while skipping if a lookalike model has already been computed for an audience in (4)
- Advertiser seed audiences
Precomputation is currently carried out on behalf of a user who has the Media DCR UI open at data change time, which limits it in two ways:
- Only computations where the user has permissions to can be precomputed.
- It only covers the audiences that participant can see, meaning their own audiences and those shared with them.
Both limitations will be removed in a future release.
Creating audiences
To create audiences, you need the Create audiences permission.
To create an audience, see the steps below. Once an audience has been created, it is added to the audience list with status Computing. Once the computation of the audience has finished, the status changes to Ready.
Each audience in the list shows both the number of users (matched on userId) and the number of activation IDs. The activation ID count uses the activation ID currently selected by the base audience provider.
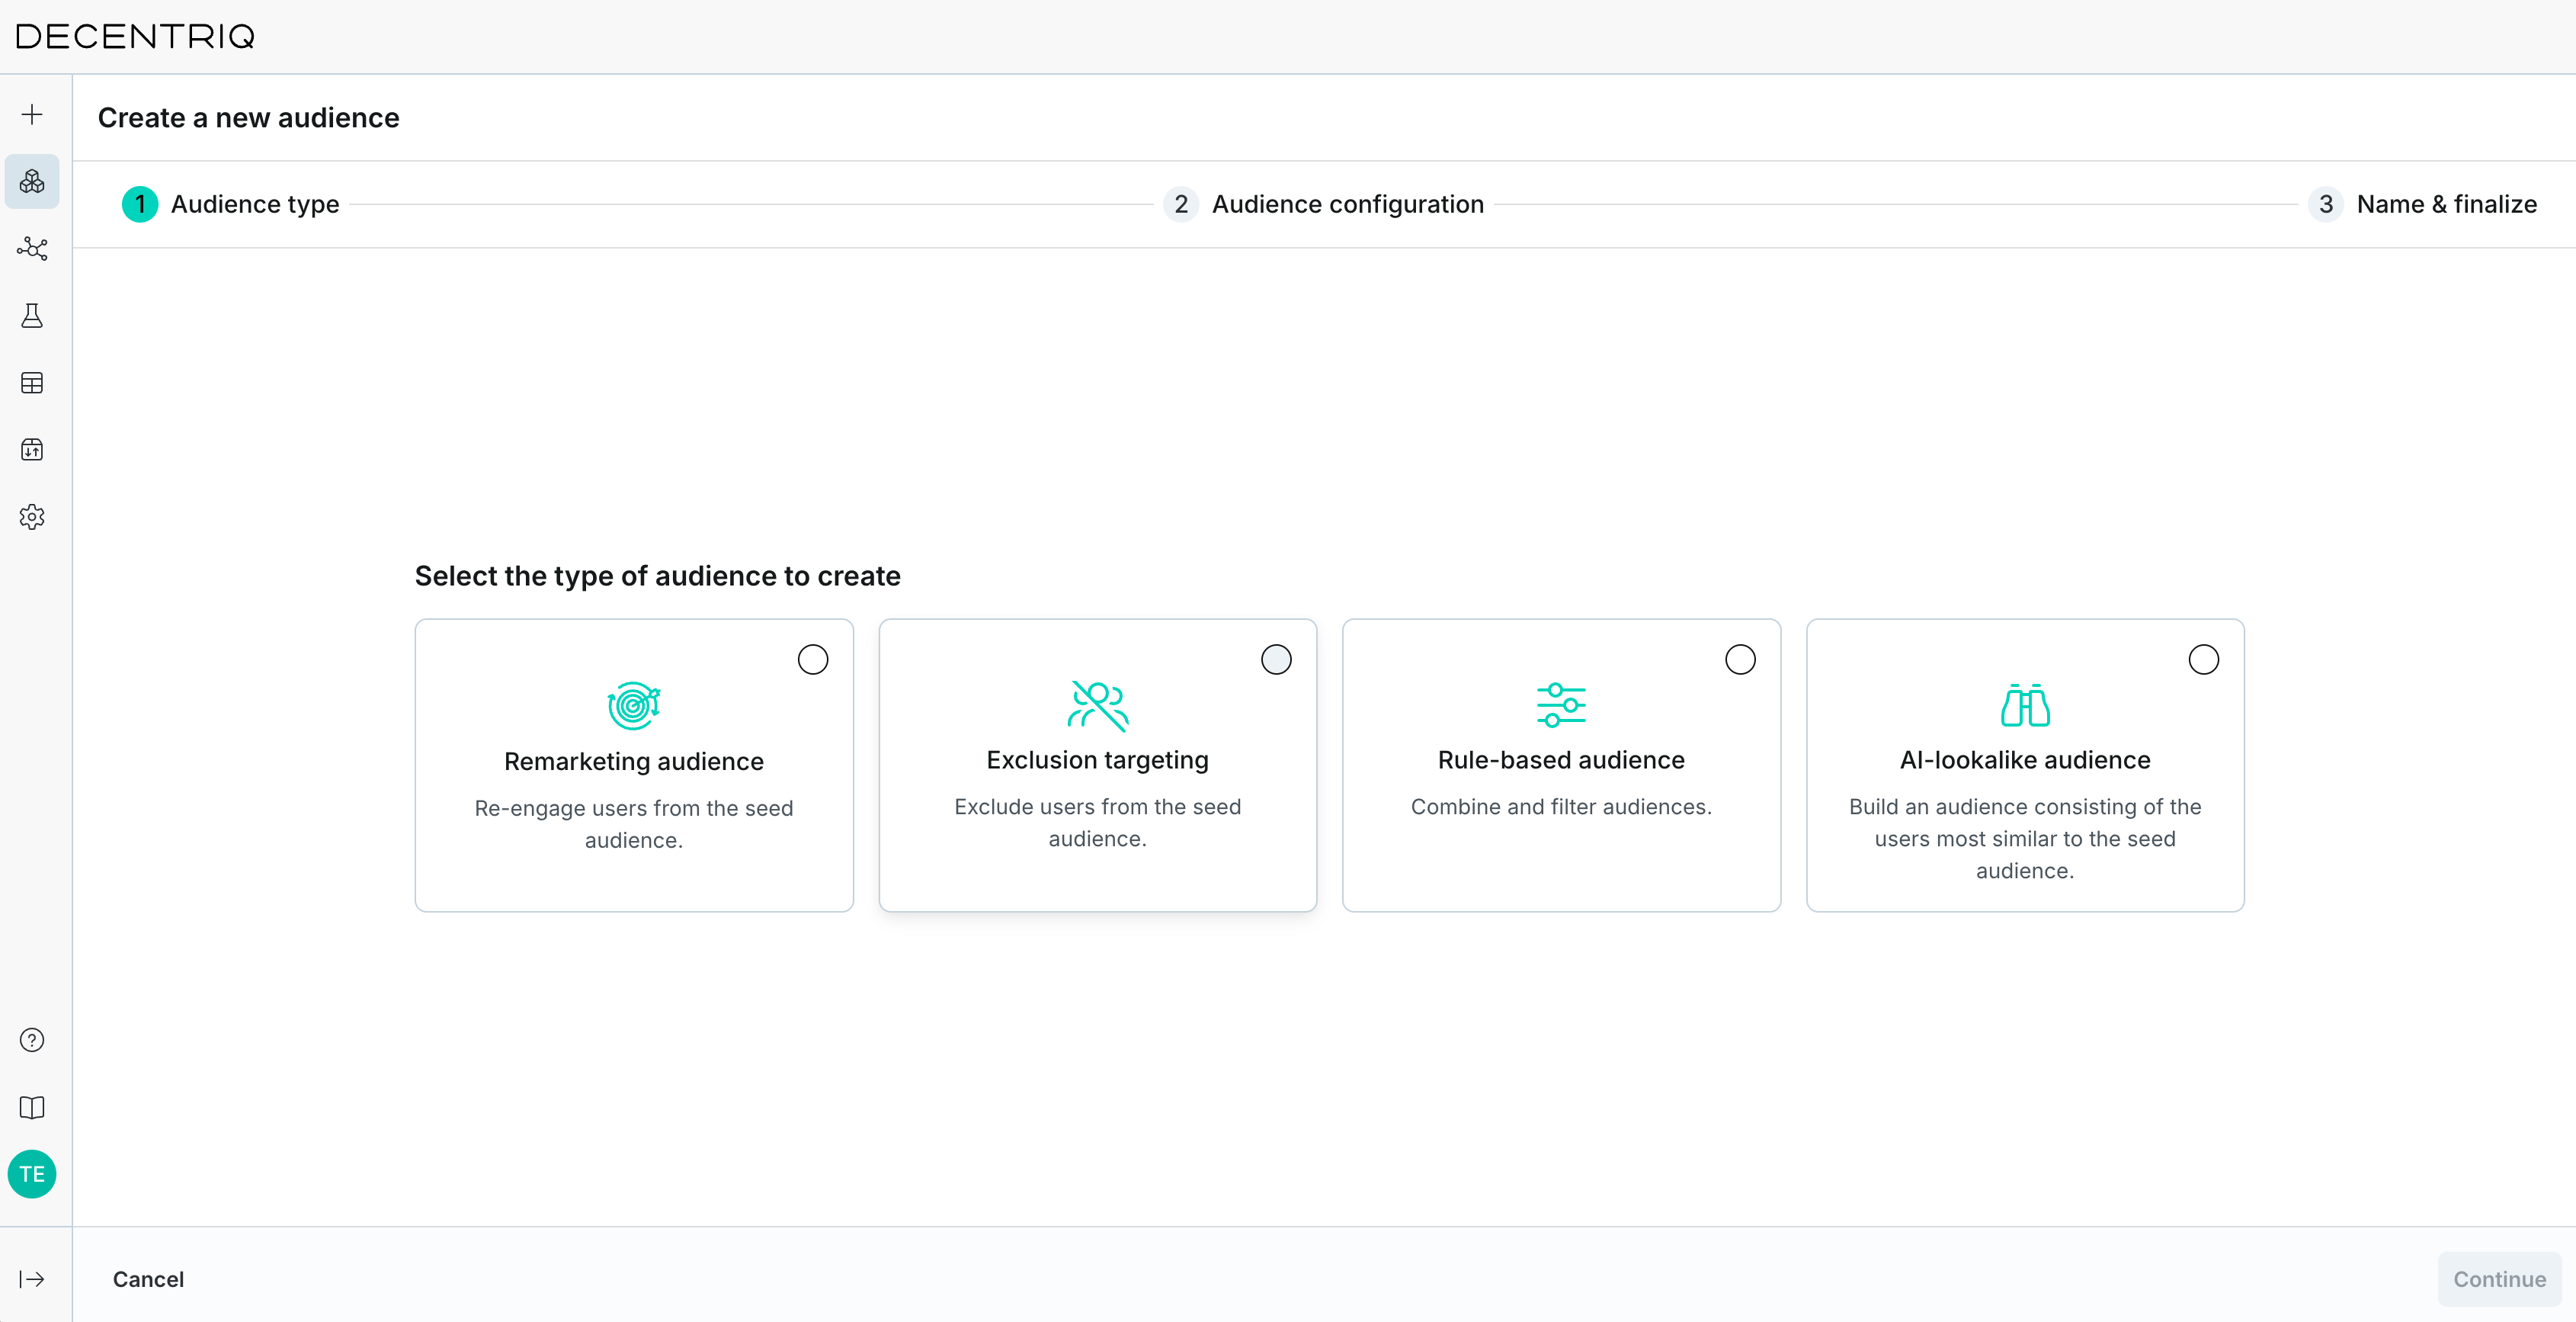
First click on Create new audience, then choose the desired audience type and see the sections below.
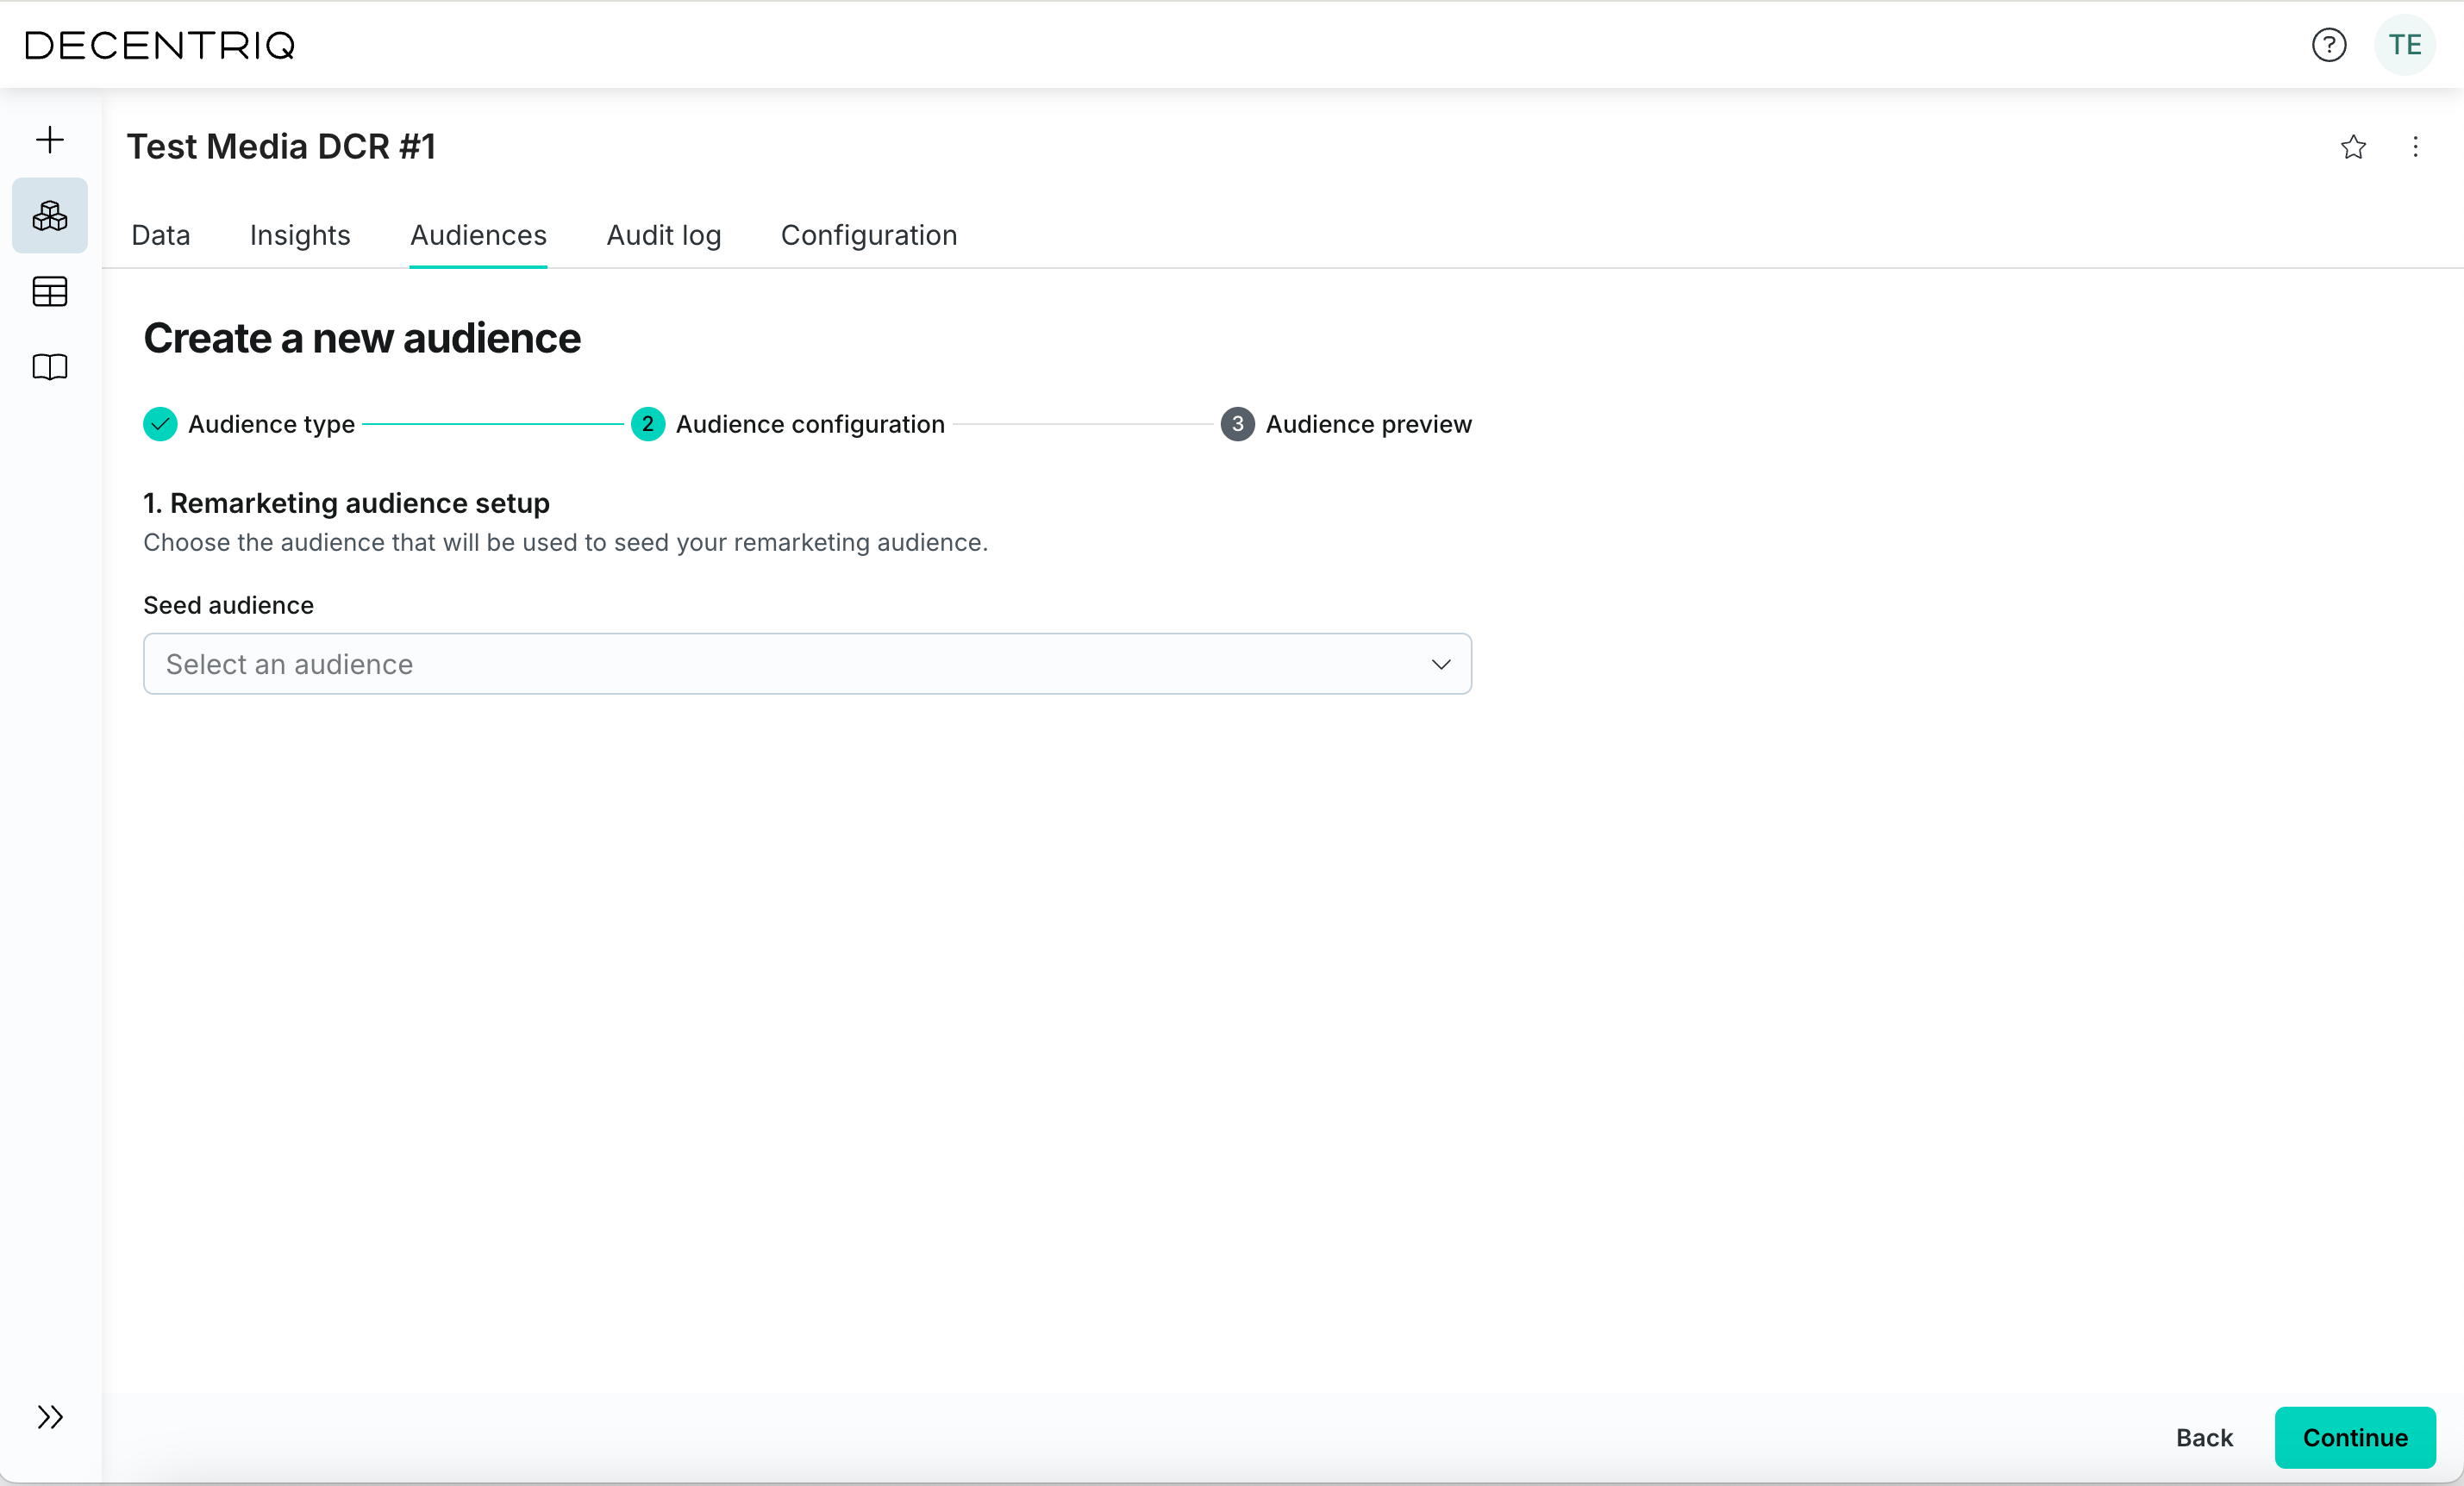
Creating a remarketing audience
Select Remarketing audiences, then choose the seed audience you wish to re-engage. Each remarketing audience contains the users that overlap between the selected seed audience and the base audience.
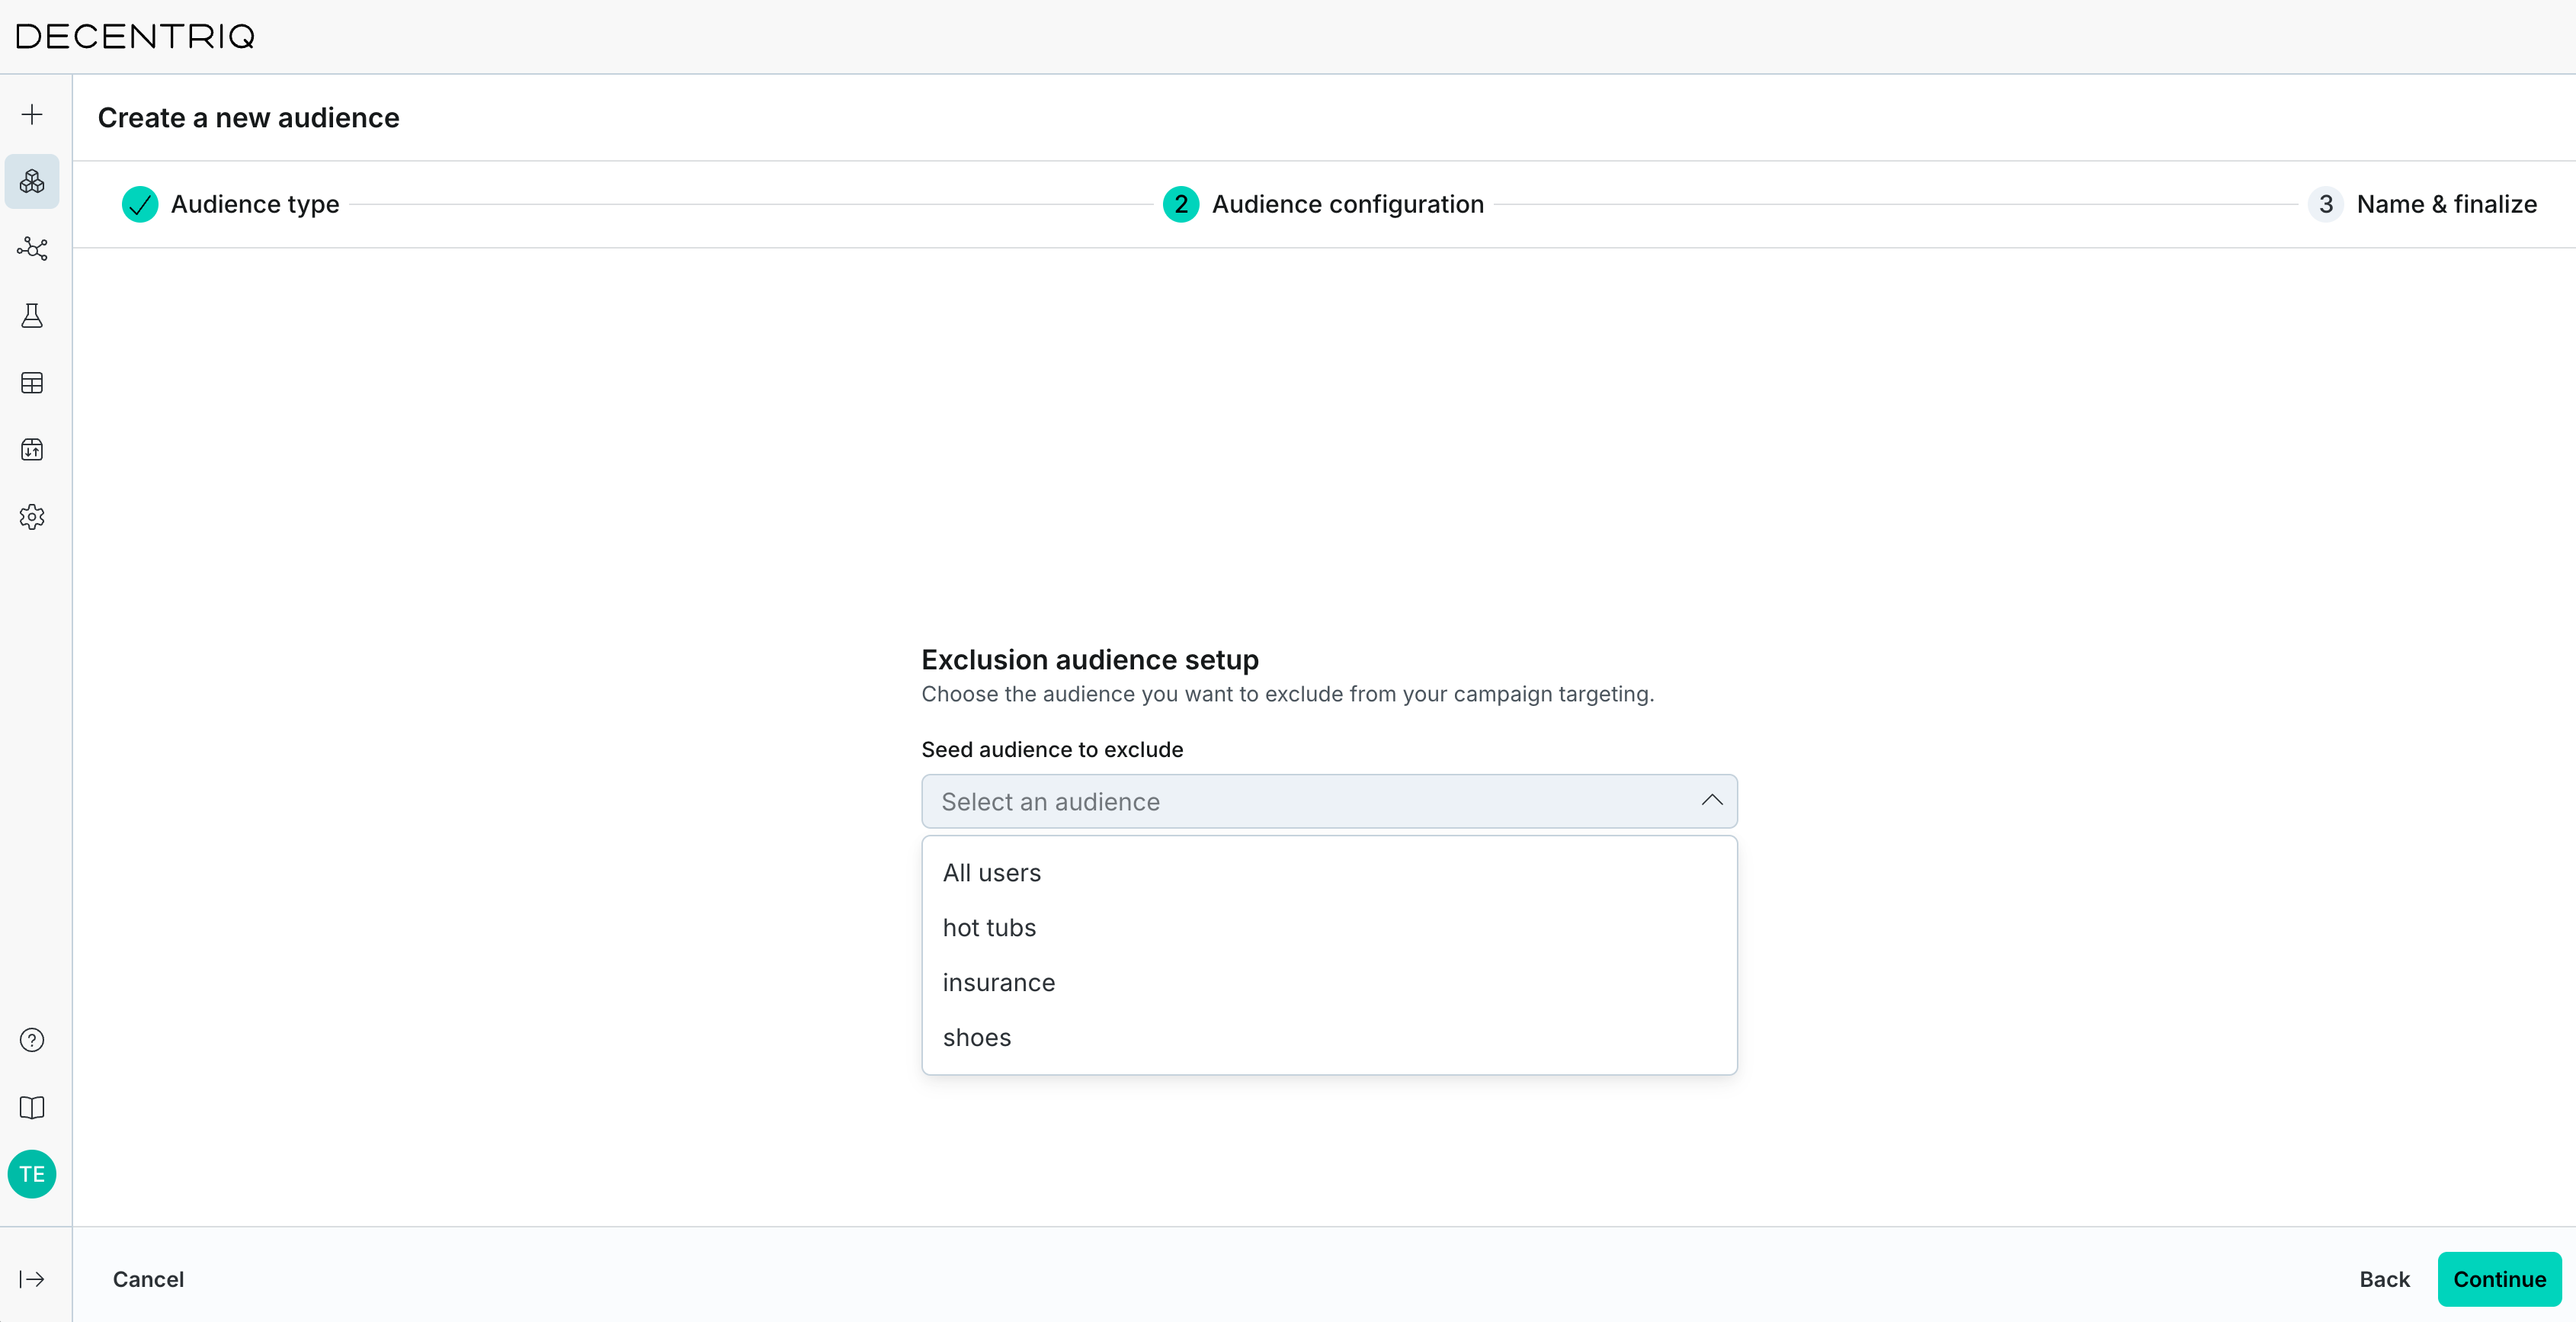
Creating an exclusion targeting audience
Select Exclusion targeting, then choose the seed audience you want to exclude from your campaign targeting under Seed audience to exclude. The resulting audience contains the users of the base audience that are not in the selected seed audience — the complement of a remarketing audience.
Exclusion targeting is useful to avoid spending media budget on users you already reach, for example by excluding existing customers from a new customer acquisition campaign.
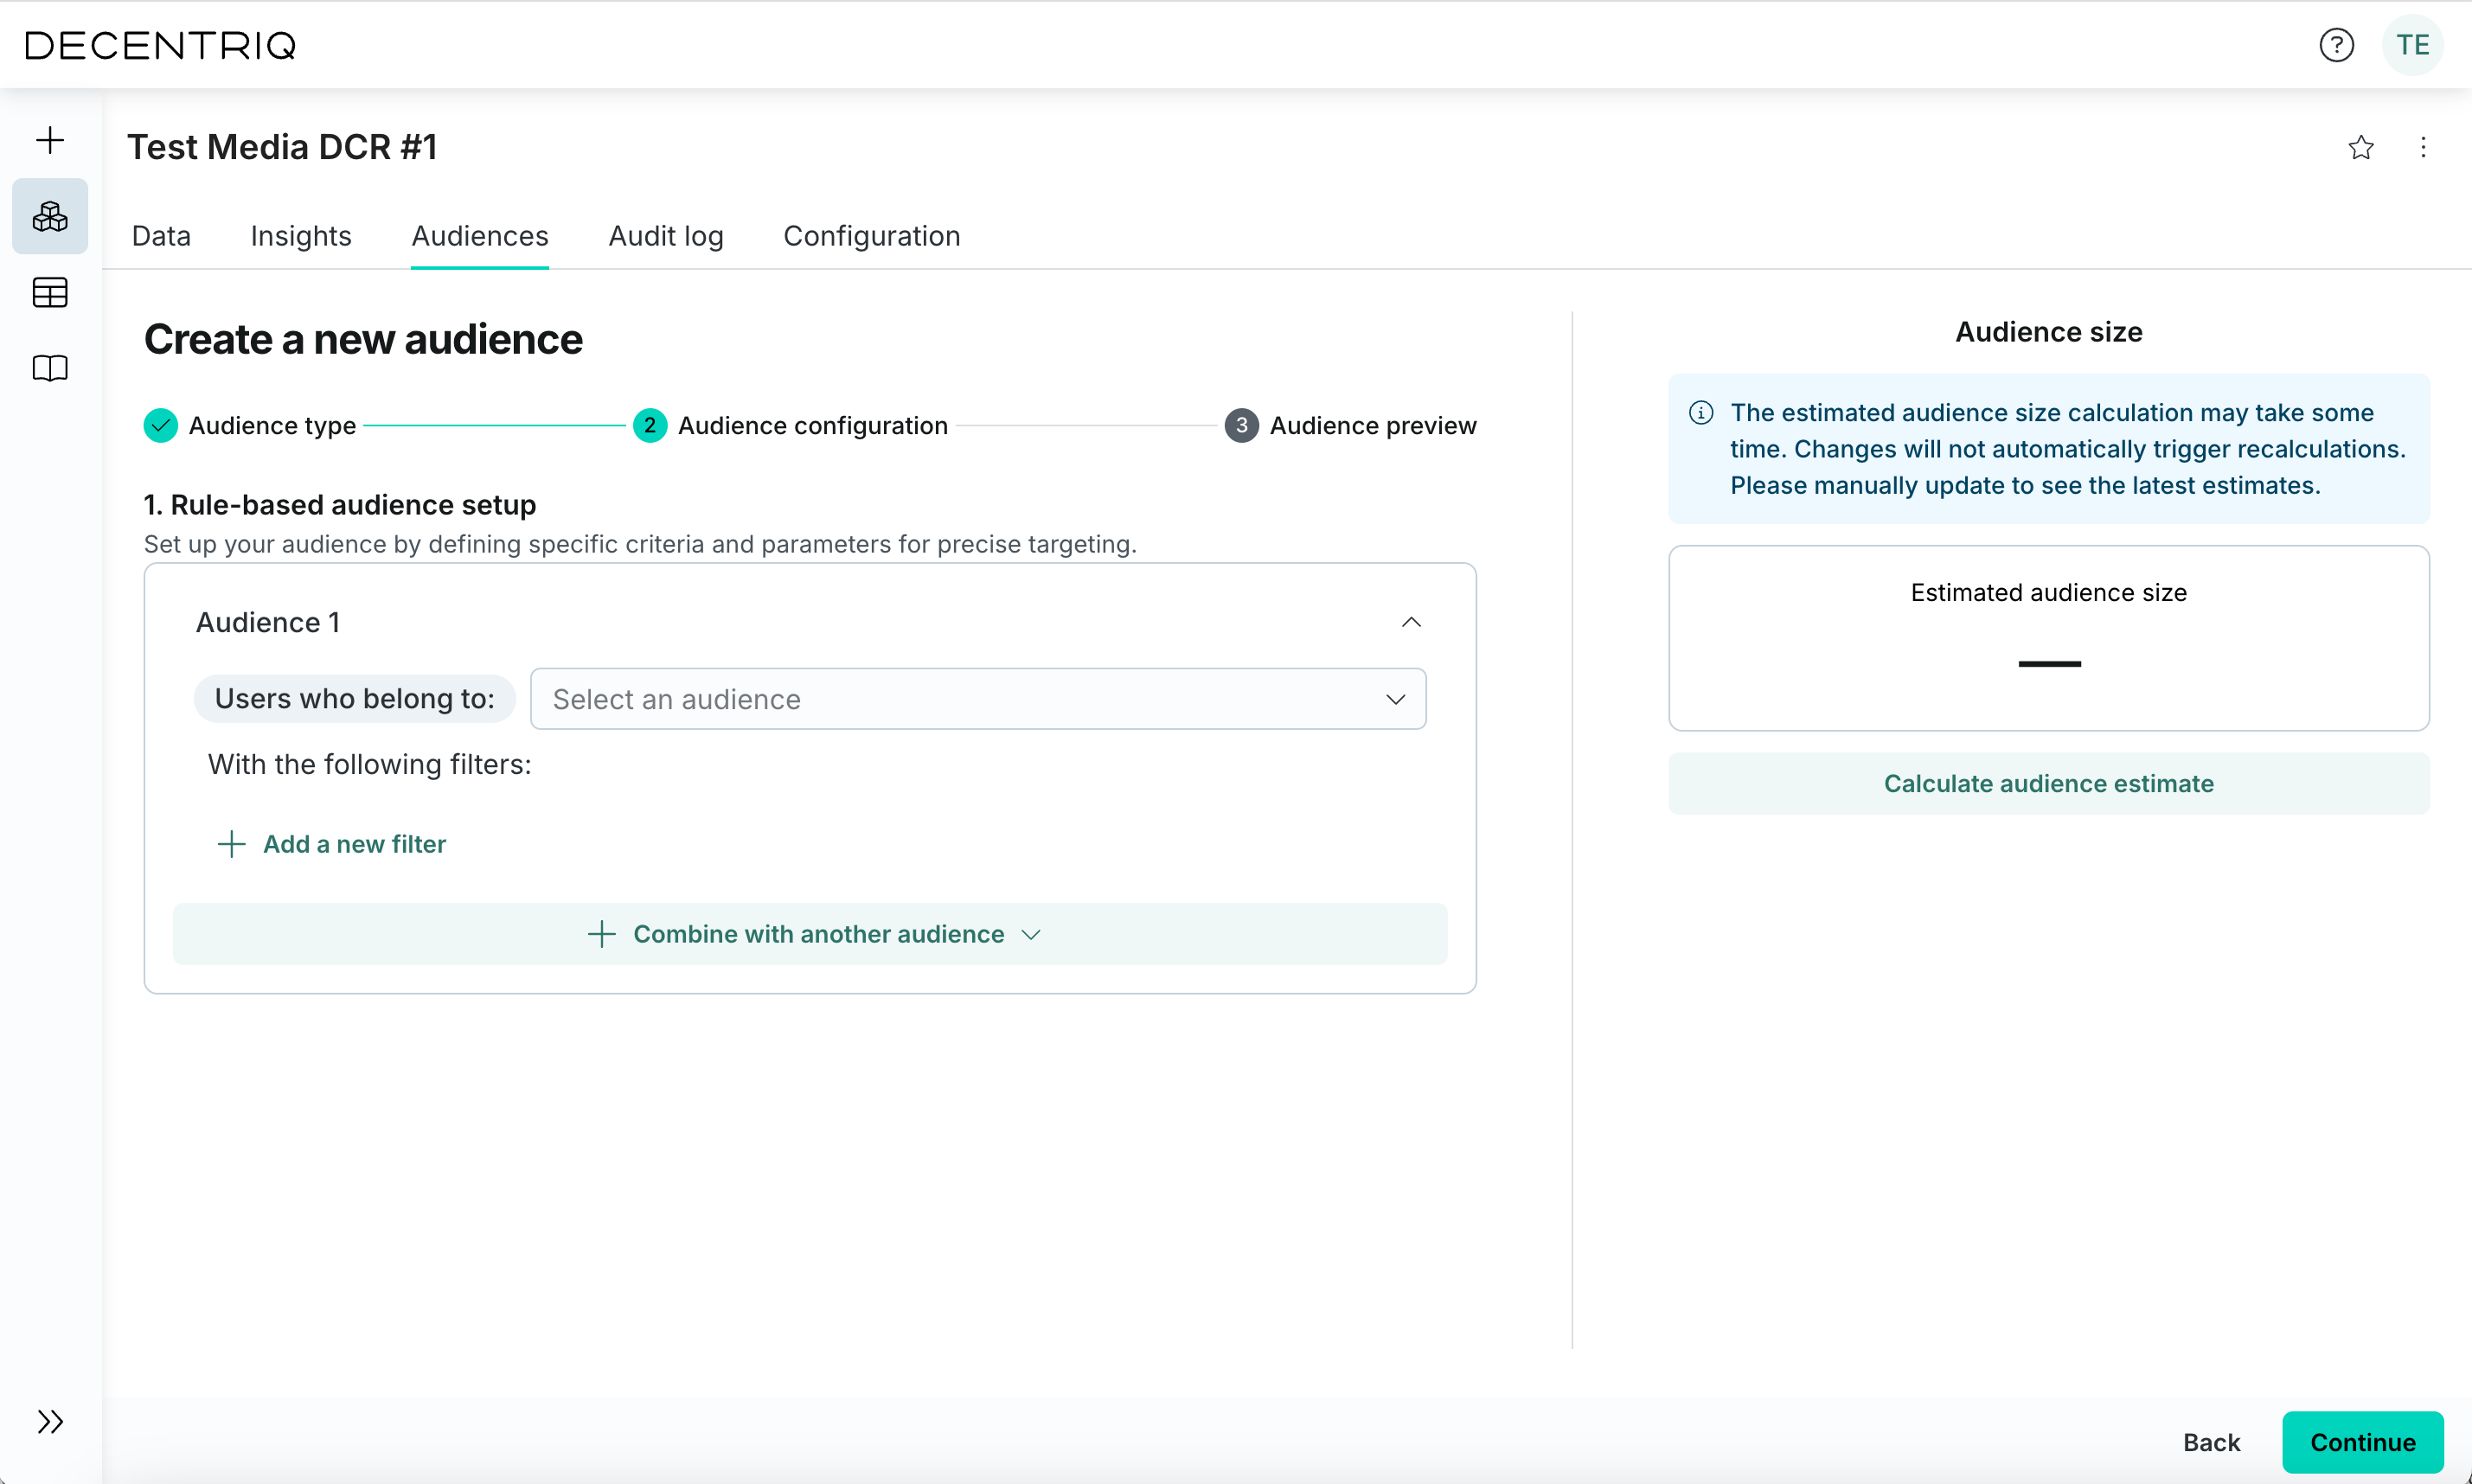
Creating a rule-based audience
Choose Rule-based audience, then combine or filter existing audiences and attributes to define the rule set.
You can craft an audience by applying several inclusion and exclusion criteria against the publisher data (or data partner data) using segments, age, and gender information.
Examples of rule-based audiences:
- Custom exclusions: Build an audience that excludes specific audiences or segments. To simply address all users outside the seed audience, use the Exclusion targeting audience type instead.
- Top-affinity segment targeting: Build an audience based on the top affinity segments identified in the audience insights dashboards
Creating an AI lookalike audience
The AI lookalike model uses machine learning to identify which users in the base audience are most similar to users in the seed audience. This provides increased reach while maintaining strict privacy guarantees since your seed audience cannot be re-identified from the lookalike audience.
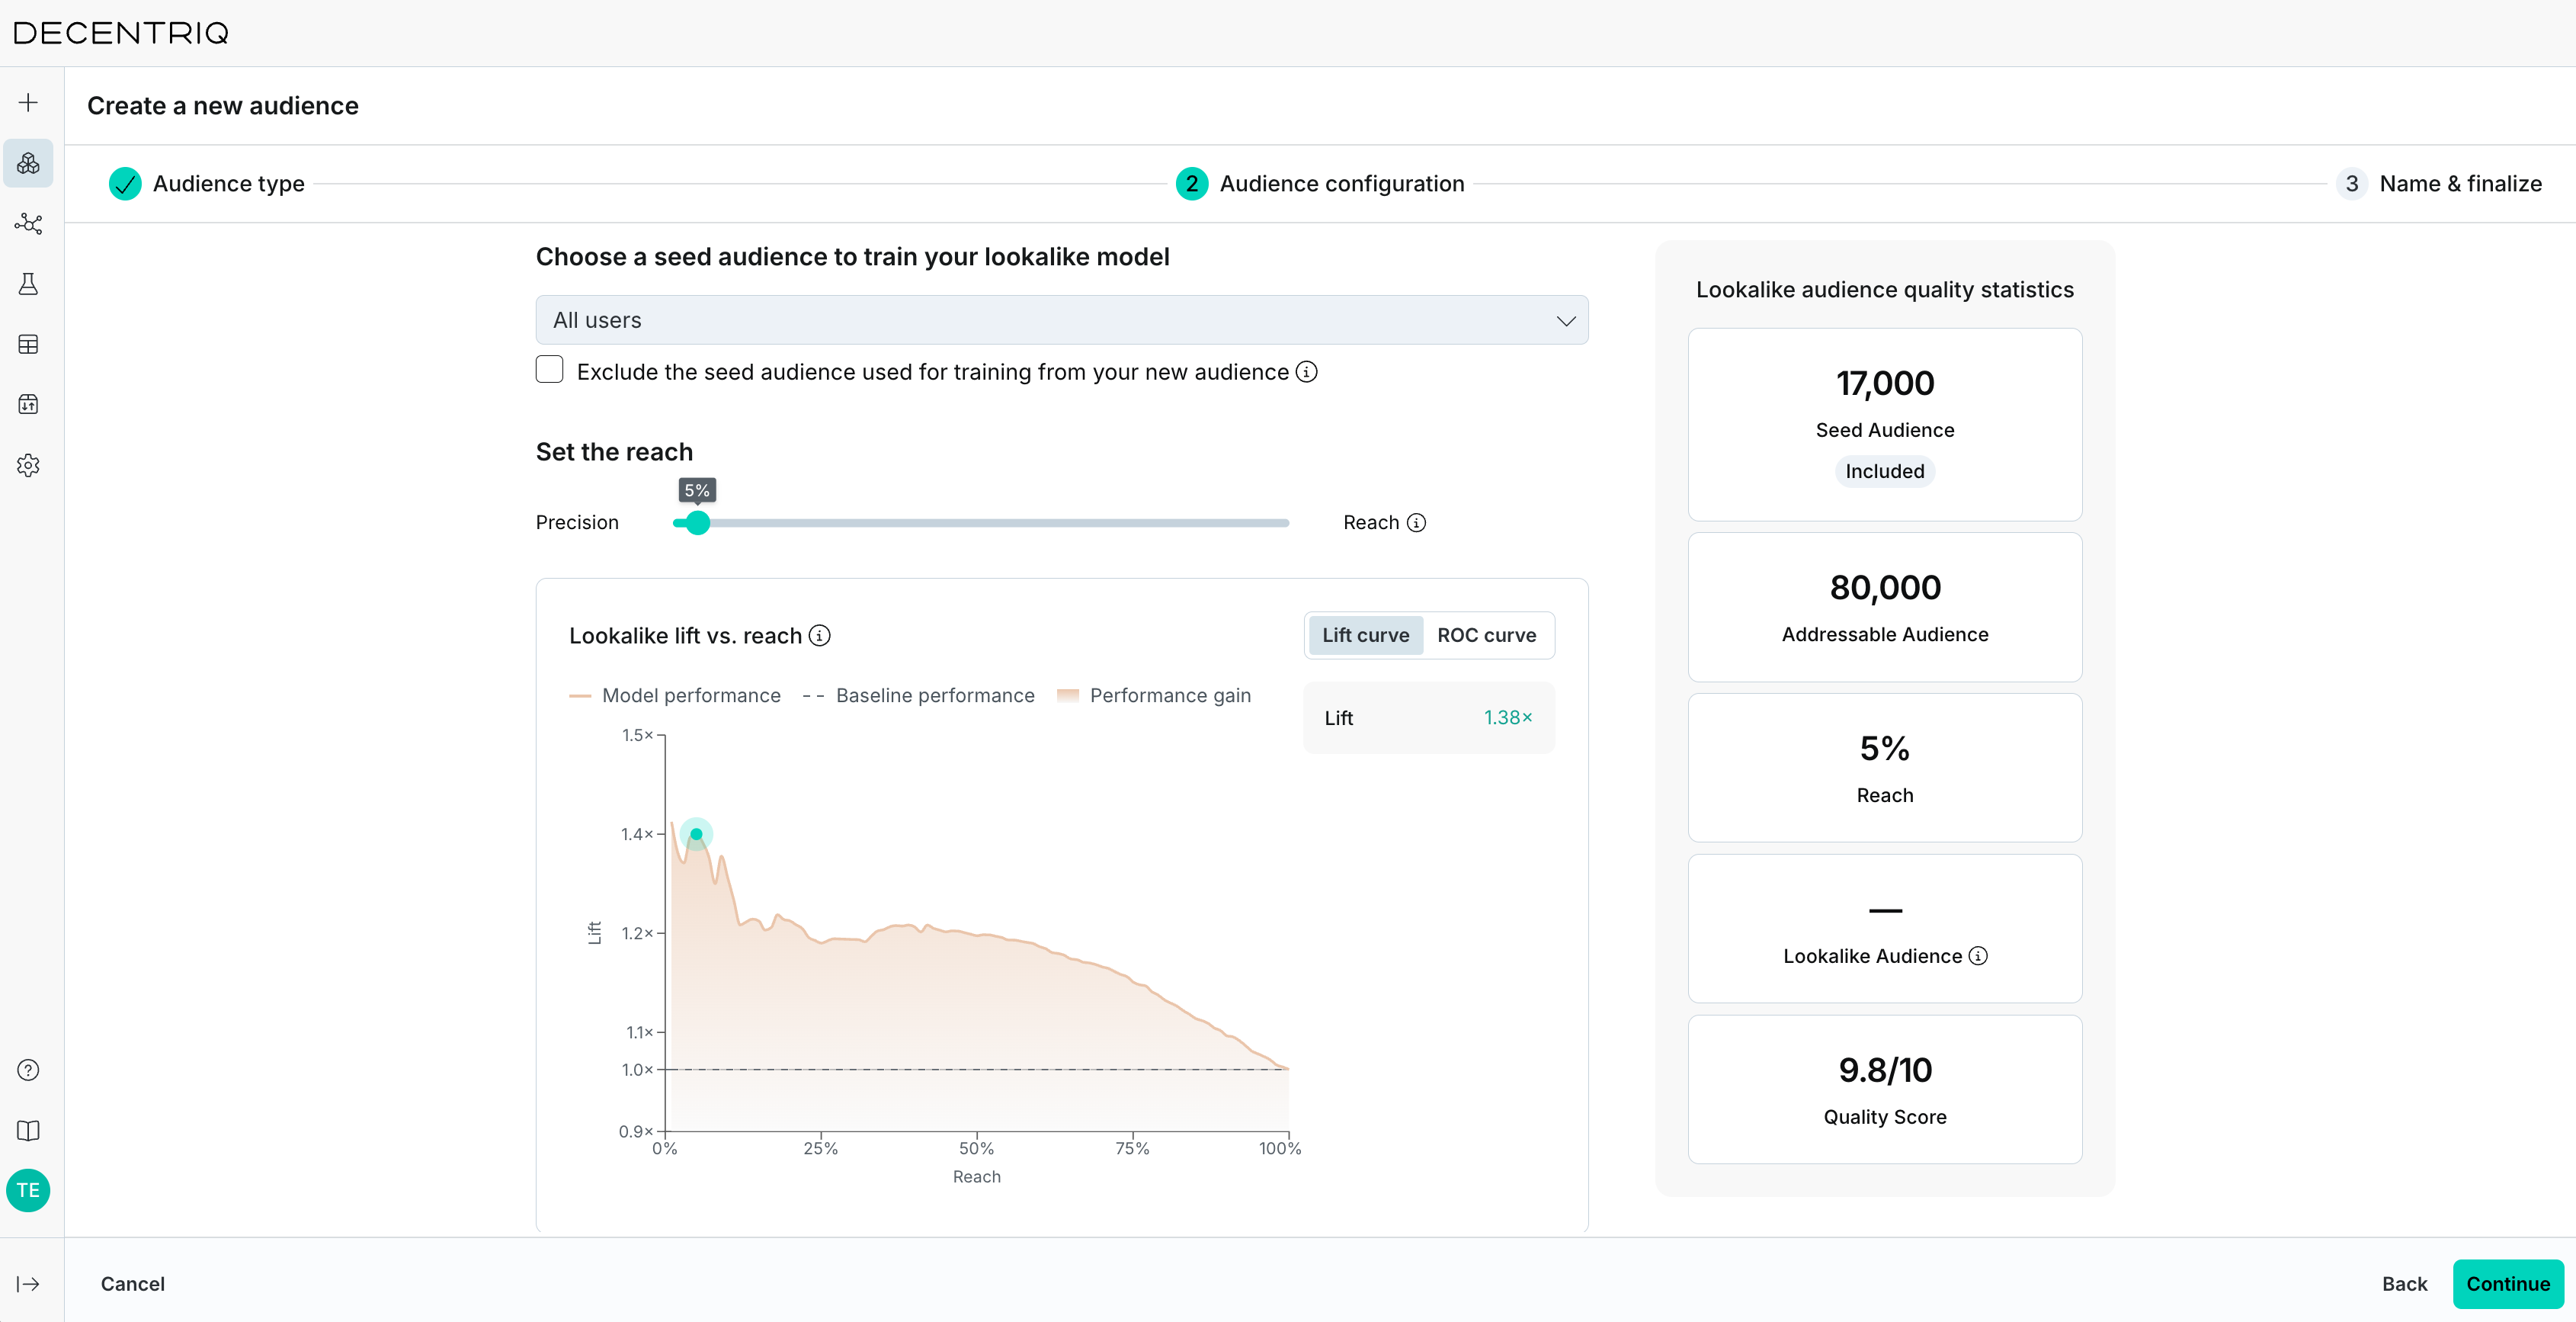
- Select AI lookalike audience from the audience type options
- Choose the seed audience to model from
- Adjust the Precision vs Reach slider to balance similarity and audience size, informed by the quality score and the quality charts (see Technical details below)
- Switch between the Lift curve and the ROC curve to judge the model performance. Both charts highlight the currently selected reach as you move the slider.
- Optionally enable Exclude the seed audience used for training from your new audience to replace the users in the overlap with the next similar users
Selecting the audience size
The sizing of the lookalike audience depends on several factors: Most importantly the media budget and desired reach, but also the audience quality score, the lift curve, and the ROC curve — they inform if the performance of the model decreases past a certain point. Some further considerations:
- Audience quality scores should not be compared across data clean rooms, campaigns or publishers. This is a relative score, not an absolute score.
- The size of the overlap ("training dataset" in the context of the lookalike) is not required to be "huge" to reach good model performance as long as:
- The overlap is larger than the threshold of 100
- The segments provided by the base audience provider are granular enough
- Audience lookalike remains more an art than a science. Rather than building a single lookalike audience, we recommend to generate two or three (e.g. a 10% extension and a 20% extension) such that you can compare their performance and have enough campaign delivery in case the small lookalike (in this example the 10% audience) does not deliver enough.
Technical details
How it works
Training step
The lookalike model is a machine learning classifier so it requires positive/negative labels and features to get trained on. The training dataset is composed of:
Labels
- Positive labels are assigned to the base audience provider matchingIds that match with the seed audience provider matchingIds ("matched users")
- Negative labels are assigned to the base audience provider matchingIds that did not match with the seed audience provider ("non matched users"). Only a sample of negative labels are included to reach a target ratio of positive / negative label to 1:1.
Features
The model features are the segment names from the base audience provider for all matchingIds (positive and negative labels).
Before training the XGBoost classifier, Decentriq randomly split the prepared dataset into training and test sets (90% training, 10% test).
The training step can only be completed if these two conditions are met:
- There is a minimum of 100 matched users (so 90 positive labels in the training dataset). The seed audience size used for training is displayed in the quality statistics panel.
- There is a minimum of 10 and a maximum of 2000 segment names provided by the base audience provider
Testing step
After the model training is completed, the lookalike model performance is evaluated on the test dataset. Decentriq displays the corresponding lift curve, ROC curve, and audience quality score.
Lift curve
The lift curve compares the model against a random baseline at every reach level. A lift of 2 means the audience contains twice as many users similar to the seed as a random selection of the same size. The chart highlights the lift at the currently selected reach — a good lookalike audience keeps the lift well above 1 at your target reach.

ROC curve
The ROC curve indicates how the model performs:
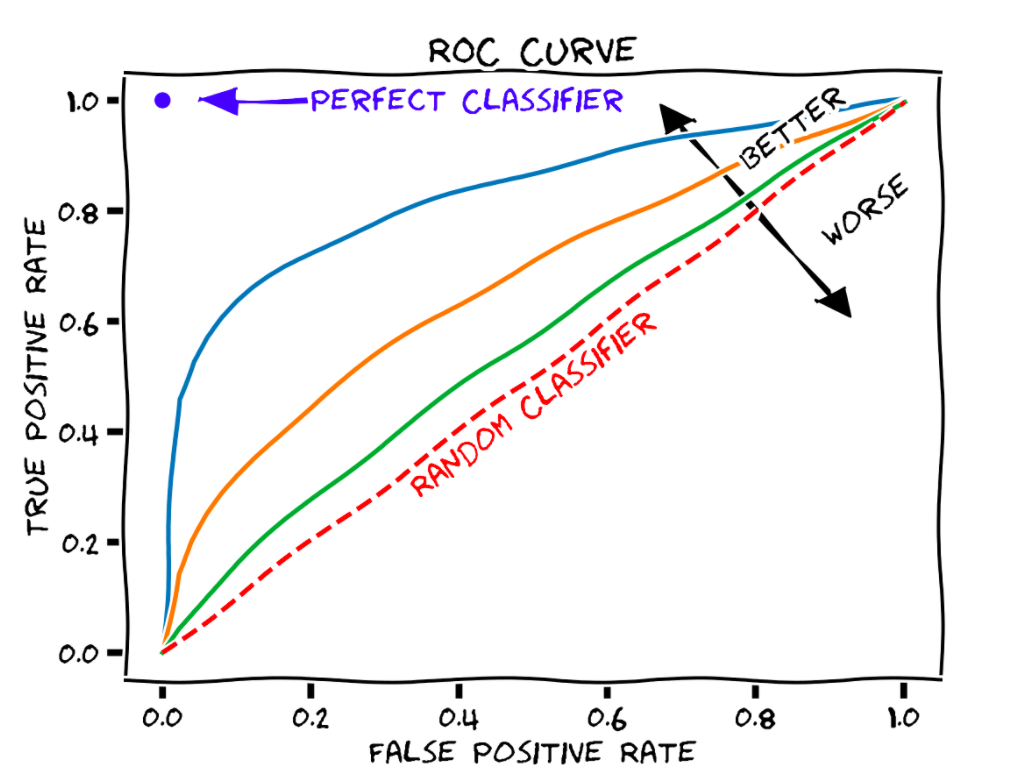
- Straight line - no performance: A ROC curve with a straight line means that the model is as good as selecting users randomly. It's obviously not the desired outcome
- Concave line - positive performance: A ROC curve with a concave line means that the model outperforms a random selection. The more the curve is concave (far from the straight line), the more the model performs
Recall is the percentage of the existing customers from the seed audience that will also be in this lookalike audience. Use the slider to see how recall changes as you adjust the precision/reach threshold.
Audience quality score
The quality score condenses the ROC curve into a single number out of 10, shown in the Lookalike audience quality statistics panel. The higher the score is, the better the audience is expected to perform.
Inference step
Decentriq runs inference on all the userIds from the base audience provider that have associated segments in order to generate a score between 0 and 1. The higher the score is, the more similar a base audience provider user is from the seed audience provider users.
Audience sizing
Decentriq sorts these users by decreasing score. The user interface allows the user to select a percentage subset from these ranked users.
Optionally the user can exclude the matched users between the seed audience and base audience from the resulting lookalike audience.
Combining lookalikes and rule-based audiences
You can generate a lookalike audience and then use it as input of the rule-based audience builder to apply further inclusion or exclusion criteria. For example, excluding an entire age group from the lookalike audience.
Collaborating on audiences
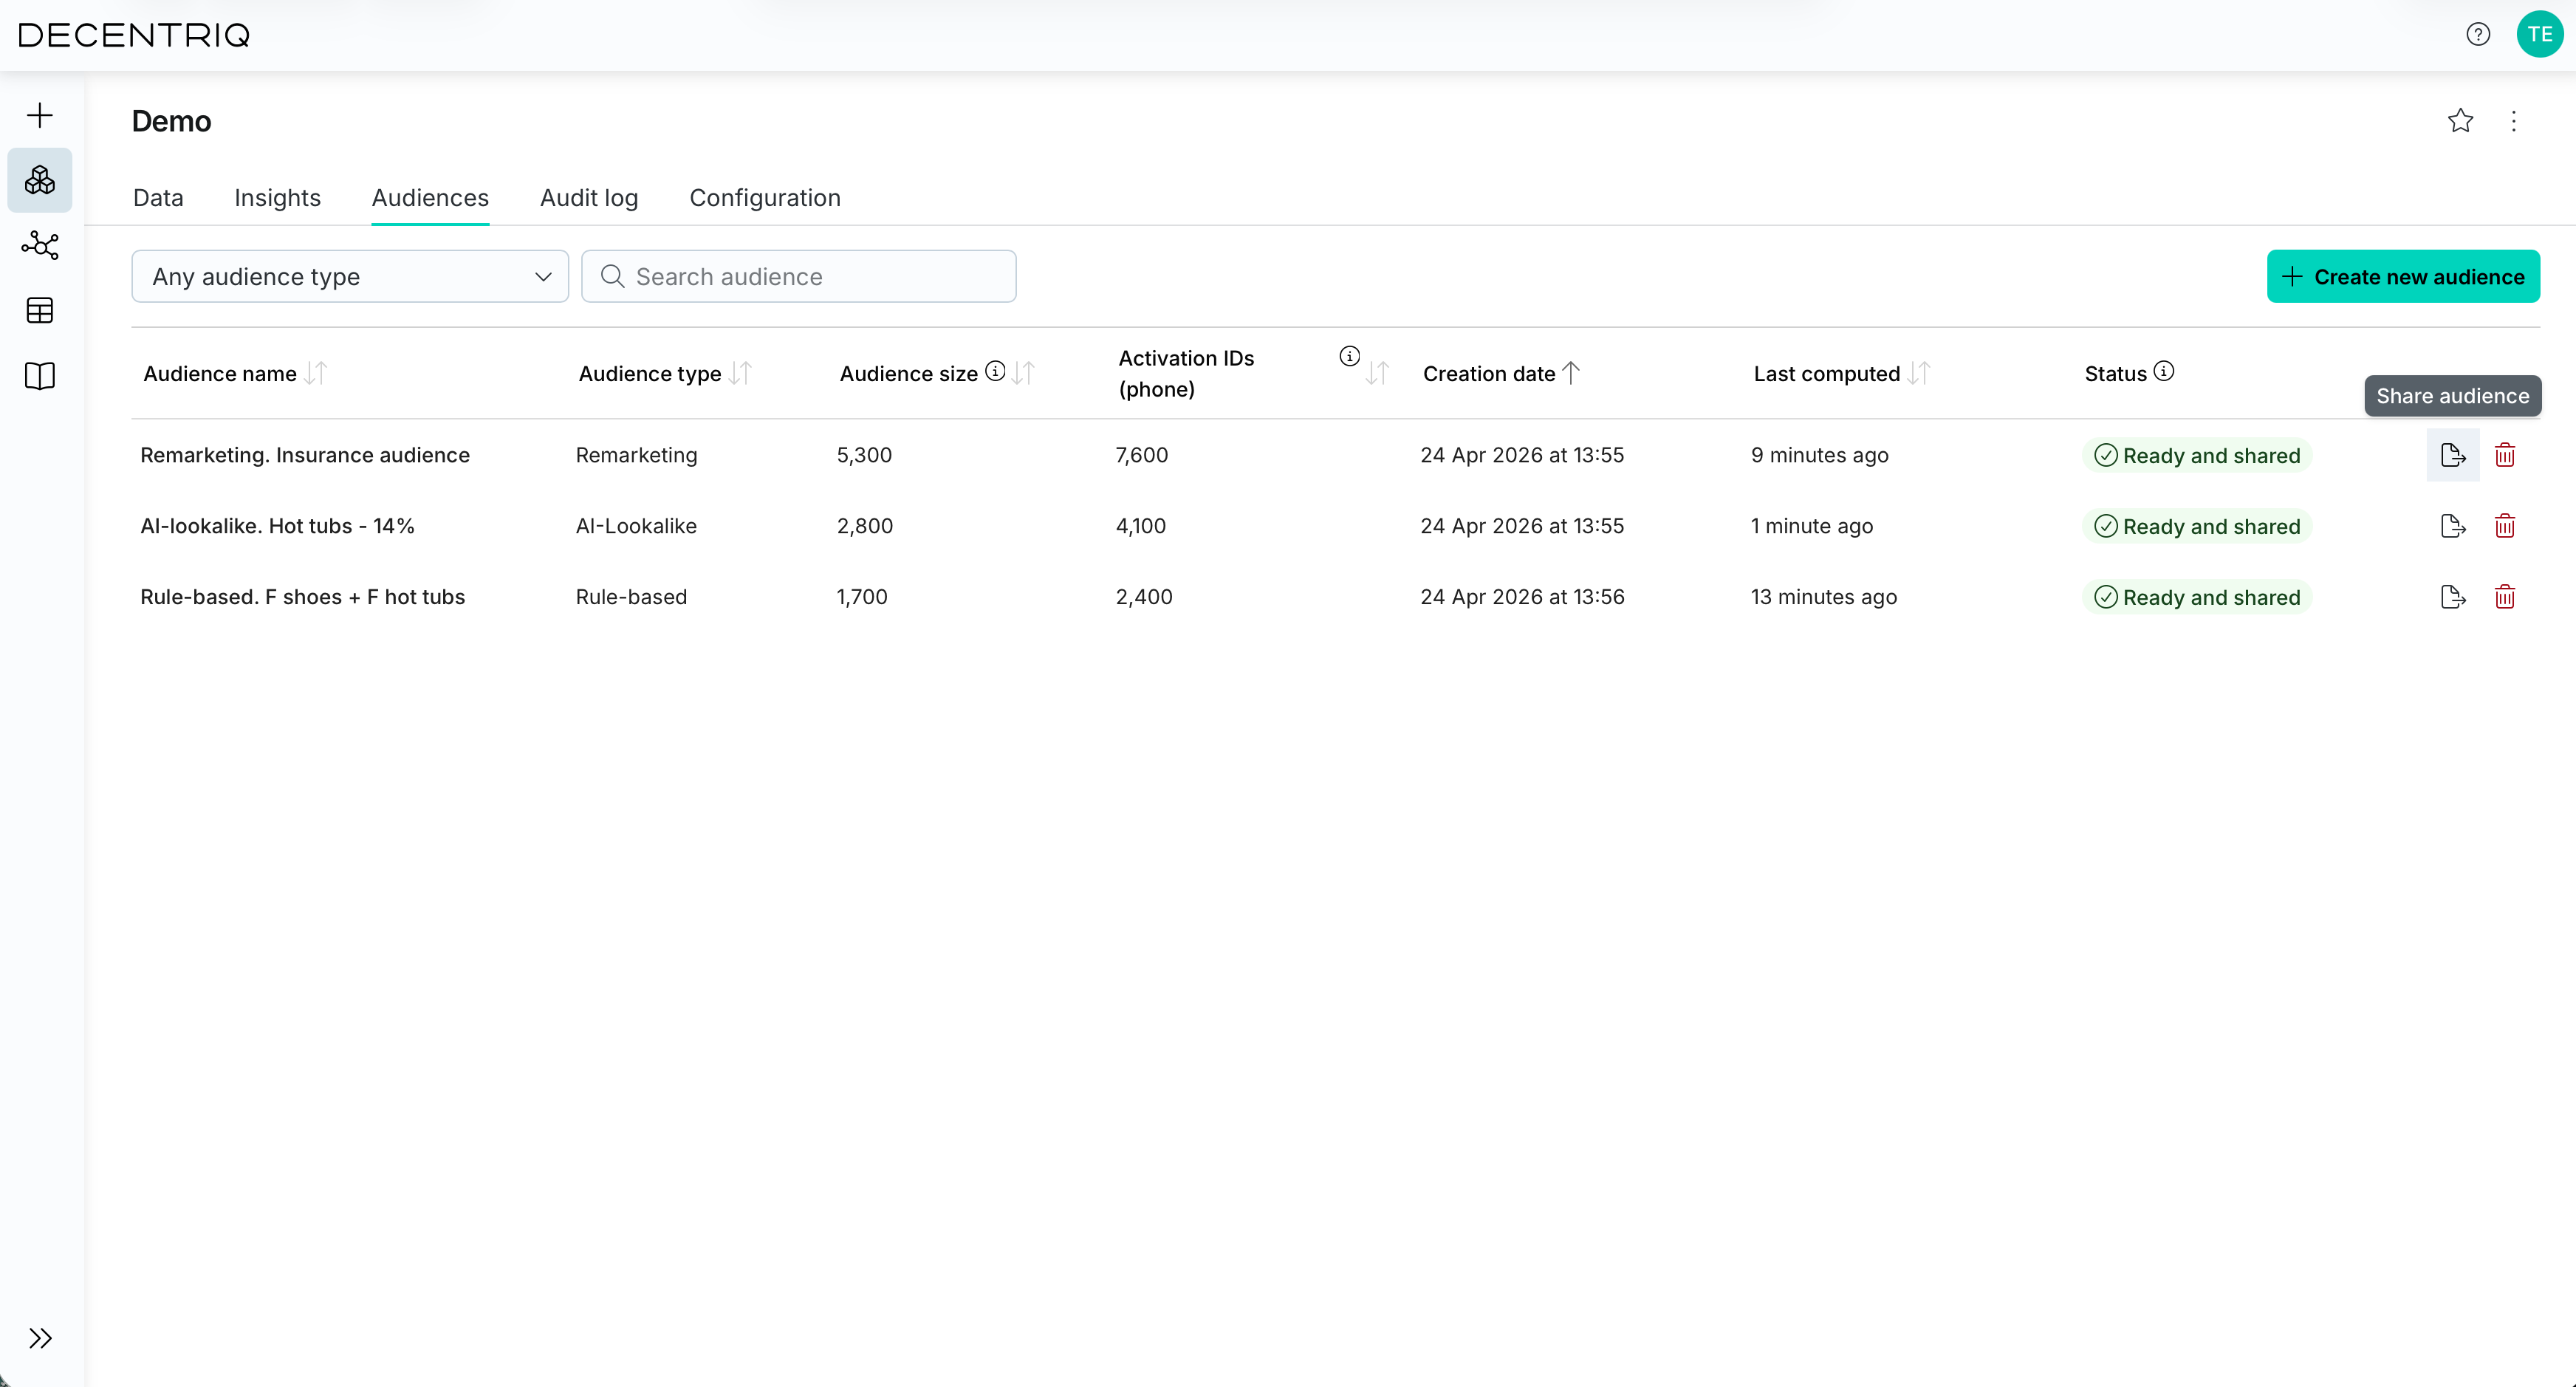
To collaborate with other participants on audiences, click on the Share button of a specific audience. The participants you share an audience with can then create additional audiences based on the shared one (if they have the Create audiences permission) or export it (if they have the Export audiences permission).
Exporting audiences
To export audiences, you need the Export audiences permission.
To export an audience, click Export (right-hand column) and choose to download or store in your datasets from which it can then be exported to external platforms.
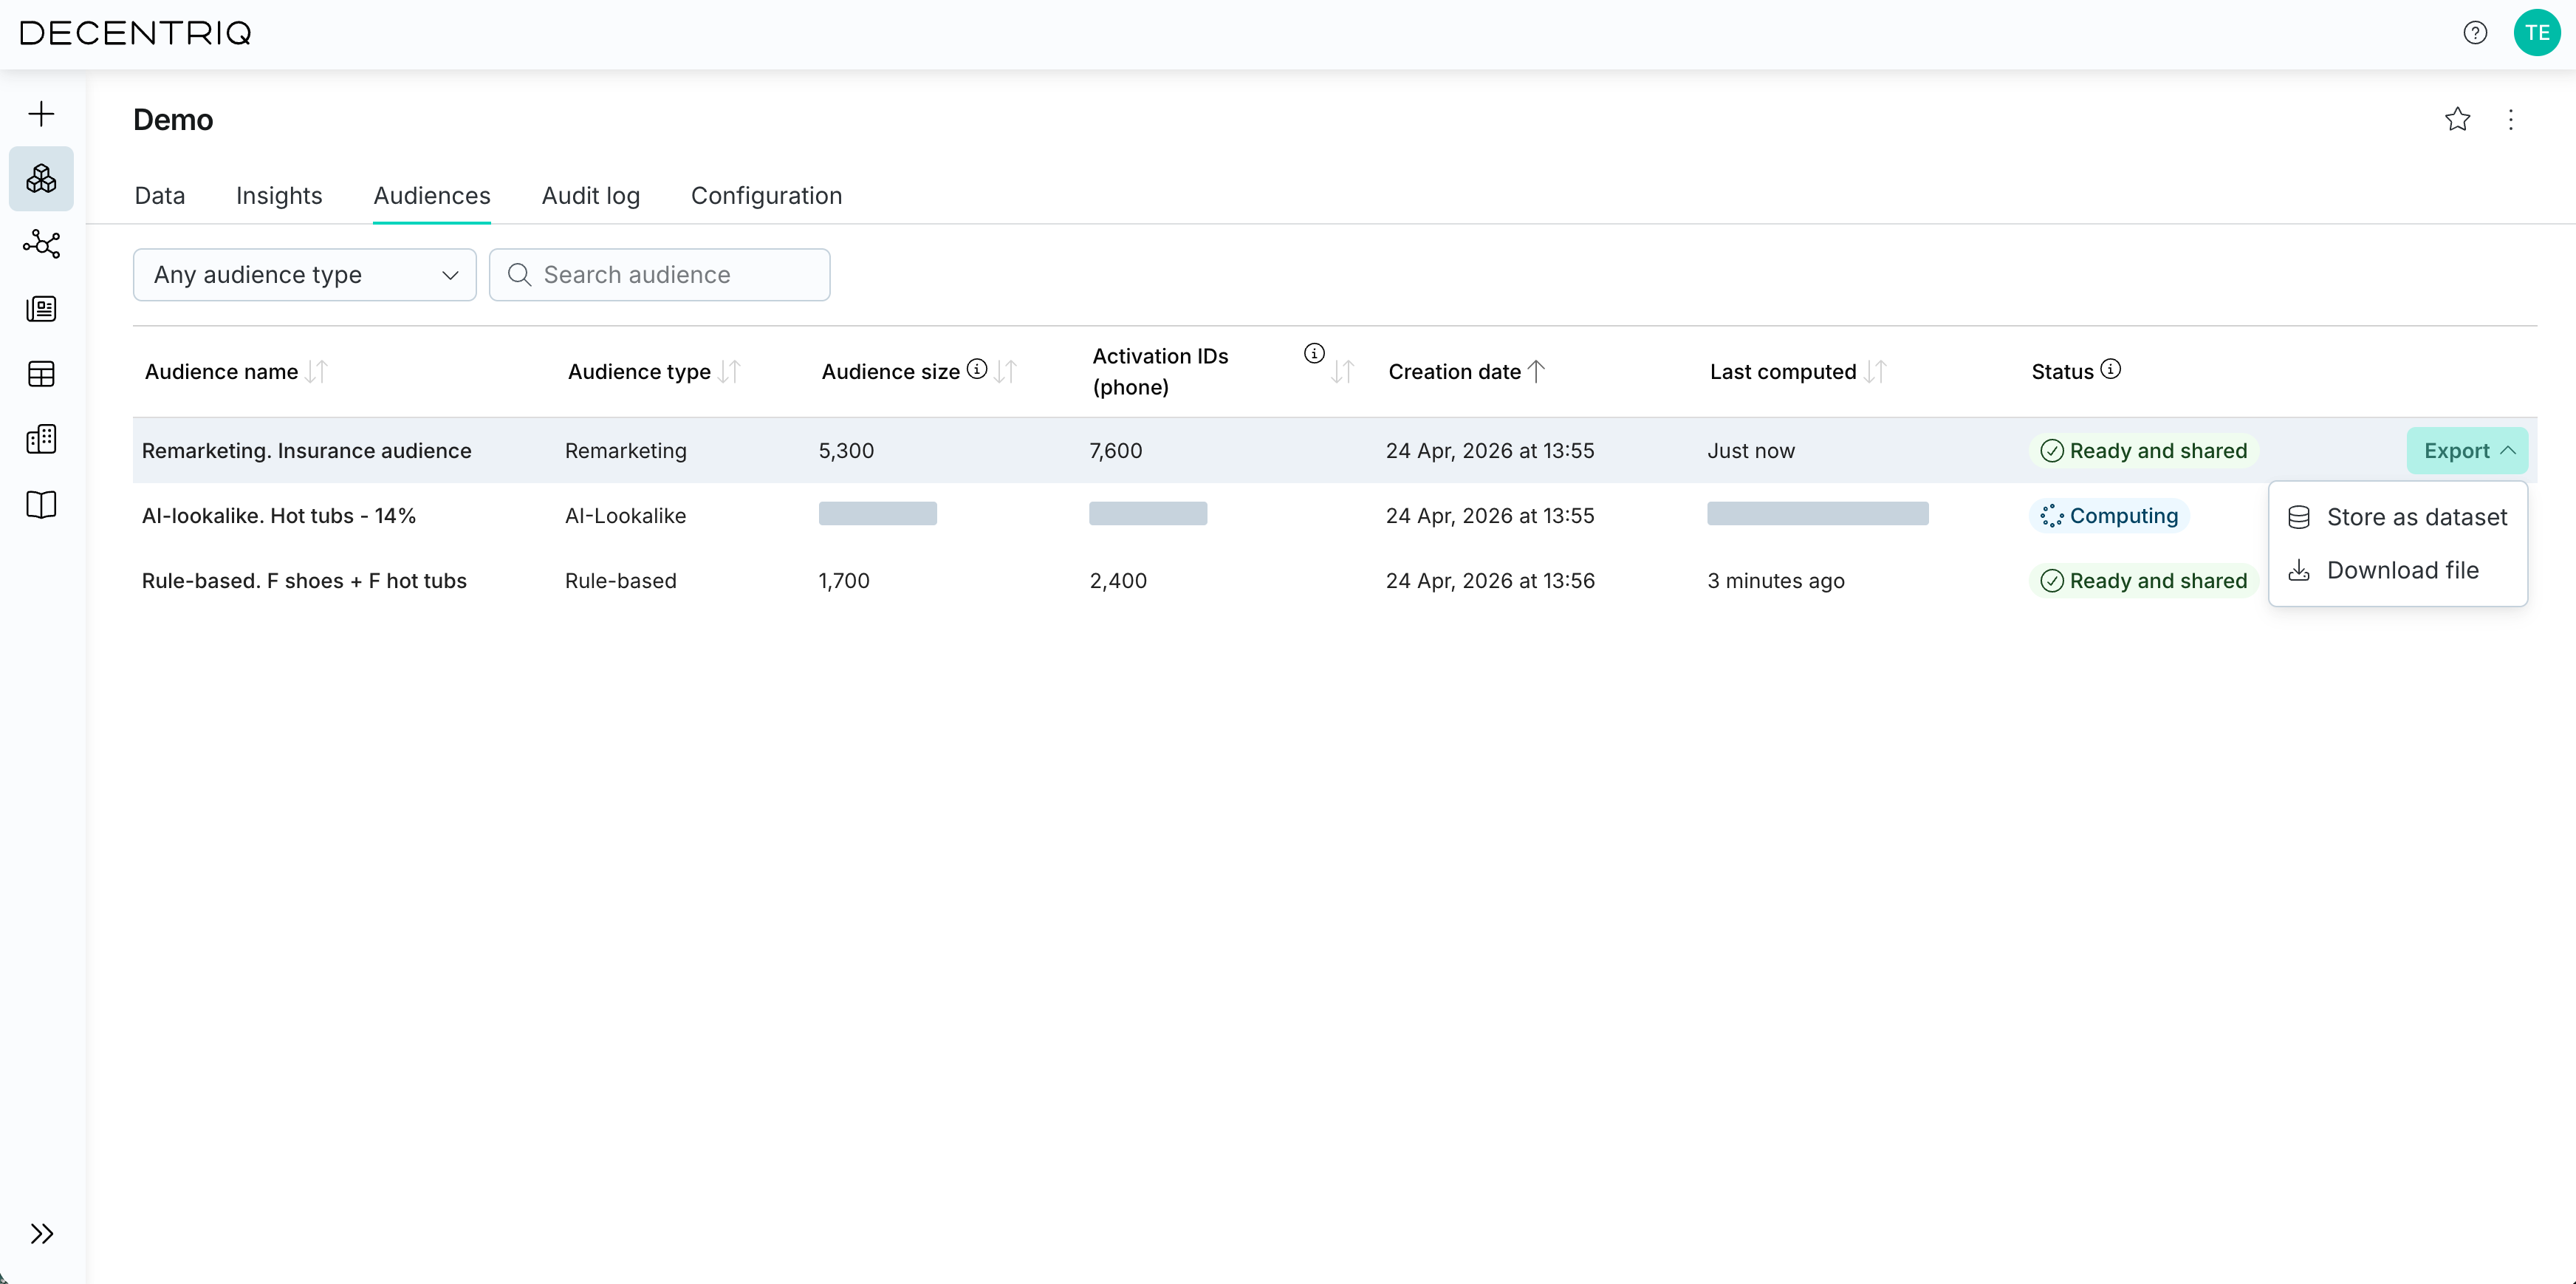
The exported audience contains the activation ID currently selected by the base audience provider, formatted as a single-column CSV without headers. To export under a different activation ID, the base audience provider switches the selected activation ID. All subsequent exports are in terms of the new activation ID.
The exported file is named after the Media DCR, the audience, and the selected activation ID: <DCR name>-<audience name>-<activation ID>.csv. The name is the same whether you download the audience or store it in your datasets.